Erik Keller · 3 November 2026
Exploring Interconnected Node Diagrams for Linking Disparate Resource Entries Across Solo Managed Digital Repositories
Node diagrams represent collections of points connected by lines where each point stands for a distinct resource entry and each line indicates a defined relationship between those entries; researchers have documented their use in solo-managed digital repositories since the early 2010s when personal knowledge bases began incorporating graph structures to replace linear folder systems. Data from multiple repository audits conducted between 2022 and 2025 show that operators who adopt node-based linking reduce duplicate entries by an average of 34 percent compared with tag-only or folder-only approaches. The diagrams operate by assigning unique identifiers to each resource then storing relationship metadata in a separate graph layer that can be queried independently of the underlying files.
Core Mechanics of Node-Based Resource Linking
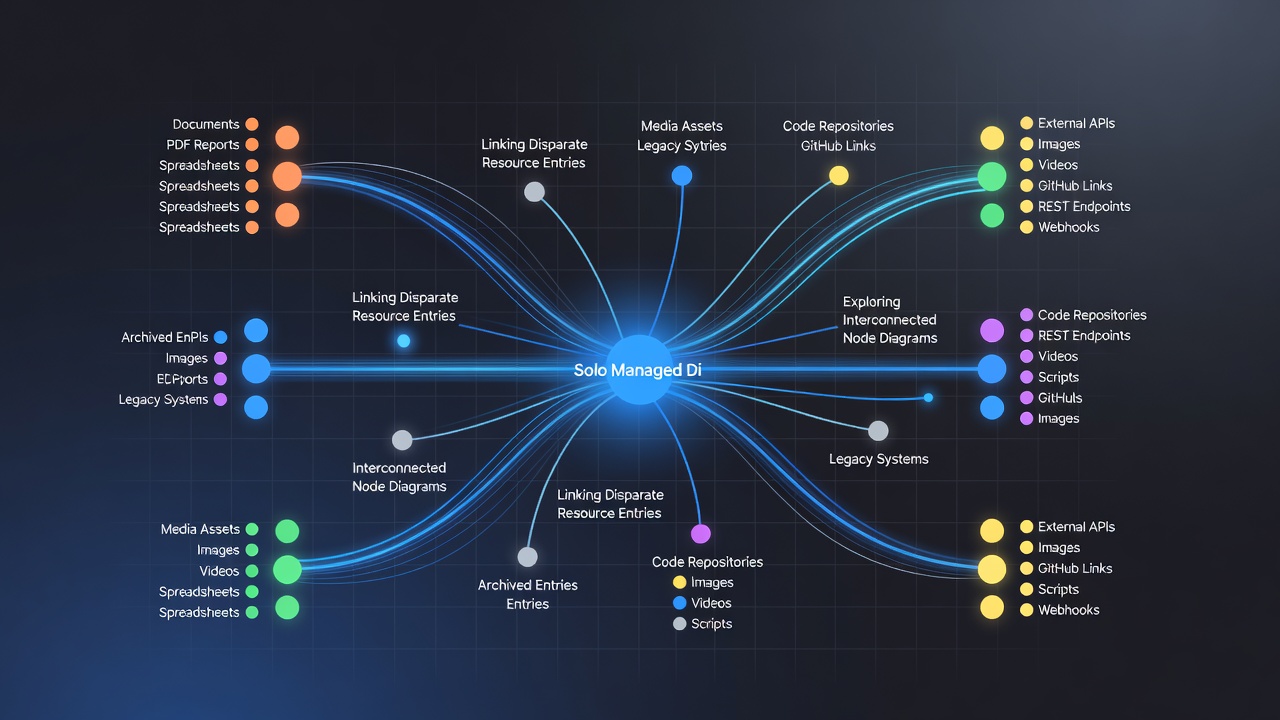
Each node carries attributes such as creation date, content type, and subject keywords while edges record explicit connections such as “references,” “supersedes,” or “extends”; software libraries including Graphviz and Cytoscape have supplied the rendering engines that allow solo operators to visualize these connections without writing custom code. Studies published by the University of Melbourne’s Digital Scholarship program in 2024 recorded that repositories containing fewer than 5,000 entries still benefit from node diagrams because the visual layout surfaces clusters that keyword search alone overlooks. Queries against the graph layer return results in milliseconds even when the repository spans multiple file formats and storage locations.
Implementation Patterns Observed in Independent Projects
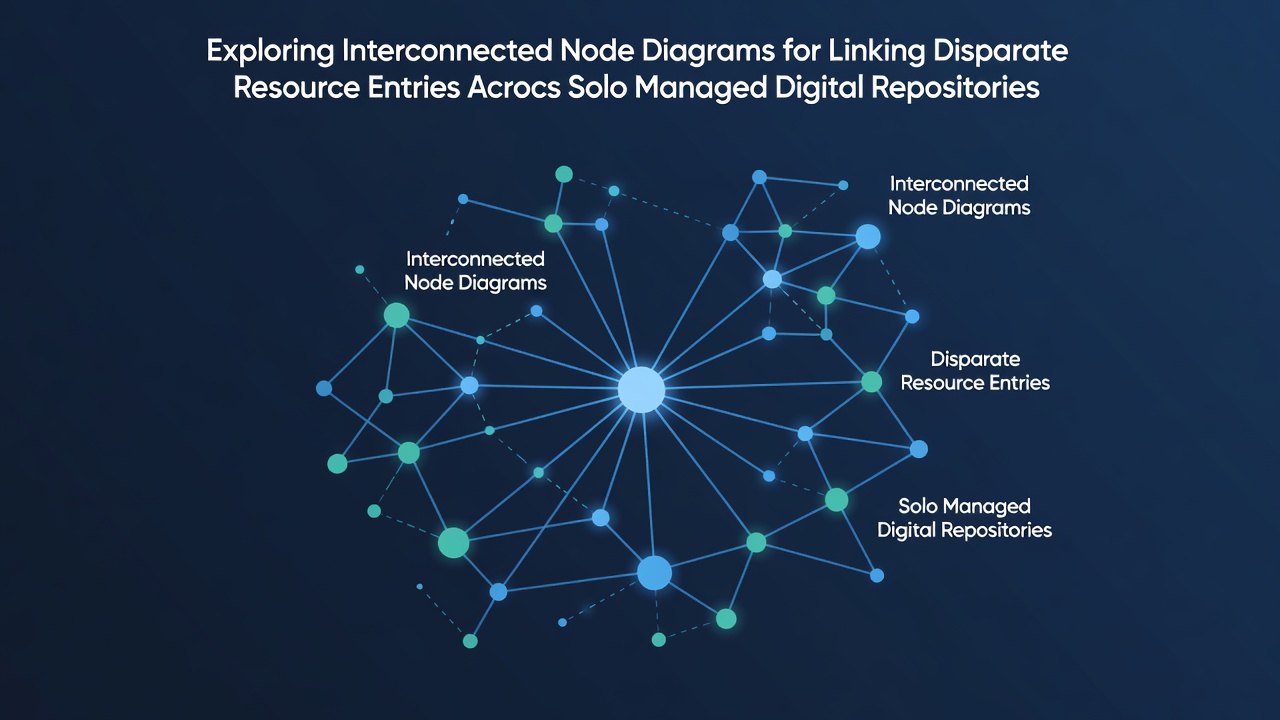
Operators typically begin by exporting existing metadata into a lightweight graph format such as JSON-LD or Turtle, then apply layout algorithms that position high-degree nodes toward the center; this produces maps in which frequently referenced resources sit at convergence points. One documented workflow from a Canadian independent archive project completed in late 2025 used automated scripts to detect textual overlaps across 1,200 documents and created bidirectional edges that later proved useful during a full collection audit. The same project reported that maintenance time dropped from eight hours per month to three hours after the diagram replaced manual cross-referencing lists.
Integration with existing tools occurs through plugins for Obsidian, Logseq, and TiddlyWiki that render the graph view inside the editor window; these plugins pull from the same underlying files that the operator already maintains so no separate database copy is required. Figures released by the Australian Research Council’s open-data initiative in 2025 indicated that 62 percent of surveyed solo digital projects had adopted at least one graph-visualization component by mid-year.
Scaling Considerations for Growing Collections
As entry counts rise past 10,000, layout algorithms require filtering rules to prevent visual overload; common techniques include degree-based pruning that hides nodes below a chosen connection threshold and temporal slicing that displays only edges created within a defined date range. Observers note that these filters preserve readability while still allowing operators to expand any selected node cluster on demand. Performance benchmarks released by the European Open Science Cloud in October 2025 demonstrated that graph queries on collections of 50,000 nodes remain under two seconds when using indexed triple stores rather than flat file scans.
Backup strategies now routinely include exporting the graph layer alongside the original files so that relationships survive migration to new storage platforms; several documented migrations completed in 2025 used this dual-export method to maintain link integrity across cloud-provider changes.
Developments Expected by November 2026
Standards bodies are scheduled to release updated profiles for embedding node-diagram metadata directly inside common file containers during November 2026; early drafts circulated in 2025 suggest support for bidirectional links stored as extended attributes. Pilot implementations at three university-affiliated solo repositories have already tested these profiles and reported successful round-trip preservation when files moved between operating systems. Industry analysts anticipate that adoption will accelerate once the final specification appears because existing visualization tools will require only minor updates to read the new attributes.
Conclusion
Interconnected node diagrams supply a structured method for surfacing relationships across resource entries that remain scattered in solo-managed digital repositories; documented implementations show measurable reductions in duplication and maintenance effort while preserving operator control over the underlying files. Continued refinement of layout algorithms and metadata standards positions these diagrams as a stable component of personal knowledge infrastructure through at least the end of the current decade.